Free tools · AI crawler access checker
Is your site blocking AI?
The AI crawler access checker shows which AI crawlers can fetch your site and what stops the rest, from robots.txt rules to CDN blocks. No signup.
3 free checks per hour · results cached 24 hours per site · we identify ourselves on every request.
Sample data
Where the points went
- −18Claude-User and Claude-SearchBot are refused by a CDN bot ruleFix: allow verified AI crawlers in your CDN’s bot settings
- −11PerplexityBot is disallowed on /guides/Fix: delete the PerplexityBot group in robots.txt
Live answer fetch
- ChatGPT-User robots.txtlive 200 Can fetch
- Claude-User robots.txtlive 403 Blocked by the CDN
- Perplexity-User robots.txtlive 200 Can fetch
Index
- OAI-SearchBot robots.txtlive 200 Can fetch
- Claude-SearchBot robots.txtlive 403 Blocked by the CDN
- PerplexityBot robots.txtlive 200 Disallowed on /guides/
- Applebot robots.txtlive 200 Can fetch
Training
- GPTBot robots.txtlive 200 Can fetch
- Google-Extended robots.txtnot requested Opted out
Where the points went
- −4Applebot gave no clear answer in time and is reported as unknown, never as allowedFix: run the check again later
Live answer fetch
- ChatGPT-User robots.txtlive 200 Can fetch
- Claude-User robots.txtlive 200 Can fetch
- Perplexity-User robots.txtlive 200 Can fetch
Index
- OAI-SearchBot robots.txtlive 200 Can fetch
- Claude-SearchBot robots.txtlive 200 Can fetch
- PerplexityBot robots.txtlive 200 Can fetch
- Applebot robots.txtlive, no answer Unknown
Training
- GPTBot robots.txtlive 200 Can fetch
- Google-Extended robots.txtnot requested Opted out
Read your result
Every verdict points to a fix.
Each crawler gets one of five verdicts. Fix the crawlers that fetch pages for live answers first, then the index crawlers. Training crawlers are your choice and never count against the score.
- Can fetch
robots.txt lets the crawler in, and a live request returned your page.
Nothing to fix. Check that the pages are ready to quote, and watch for a new rule that shuts the crawler out later.
- Disallowed
A robots.txt line keeps the crawler out of the whole site, or out of one folder such as /guides/.
Find the group the crawler obeys. Delete the Disallow line, or give the crawler its own group that allows the folder.
- Blocked by the CDN
robots.txt allows the crawler, but your CDN or firewall answers with a 403 or a challenge page.
Allow verified AI crawlers in your CDN’s bot settings or firewall rules, then run the check again.
- Opted out
A training crawler is disallowed. That decides future model training, not whether you can be cited today.
Keep the choice or change the rule on purpose. Make sure the rule names training crawlers only.
- Unknown
The crawler’s request gave no clear answer in time.
Run the check again later. If the verdict stays unknown, look for the crawler’s requests in your server logs.
kestreloutdoor.com scored 71. Two blocks, fixed in order.
Claude-User403Challenge page
Claude-User200Page served
Fix first · 18 points
The CDN rule
Claude-User and Claude-SearchBot get a challenge page. Claude can’t read any of your pages, even while writing a live answer. One exception for verified AI crawlers clears both.
User-agent: *Disallow: /cart/User-agent: PerplexityBotDisallow: /guides/
Then · 11 points
The robots.txt group
PerplexityBot is disallowed on /guides/, where the buying guides live. Deleting the PerplexityBot group puts the crawler back on the * rules.
- 71100AI access score, after both fixes
Afterwards
Re-check, then monitor
Both fixes bring the score to 100. Monitoring then re-runs the check on a schedule and alerts you when a plugin or firewall update shuts a crawler out again.
Disallowed?
Find the robots.txt line that blocks a crawler.
A crawler’s own rule group overrides the wildcard group, which is where most of these mistakes hide. Pick a crawler to light up the lines that crawler obeys.
1# kestreloutdoor.com/robots.txt2User-agent: *3Disallow: /cart/4Disallow: /account/5 6User-agent: PerplexityBot7Disallow: /guides/8 9User-agent: Google-Extended10Disallow: /11 12Sitemap: https://kestreloutdoor.com/sitemap.xmlGPTBotGPTBot has no group of its own and follows the * group: everything is open except /cart/ and /account/.
PerplexityBotPerplexityBot has its own group, which replaces the * group entirely. That group closes /guides/, and one line takes your buying guides out of Perplexity. Delete the group to put PerplexityBot back on the * rules.
Google-ExtendedGoogle-Extended is shut out of the whole site. For a training crawler that is a choice: reported neutrally and left out of the score.
ClaudeBotClaudeBot follows the * group, and robots.txt lets ClaudeBot in. The block is in the live request, further down.
robots.txt is a request. A firewall is a wall.
A crawler marked Blocked by the CDN passed robots.txt and hit a wall after. The check requests one page with each crawler’s user-agent and compares the response with a normal browser visit. A 403 or a challenge page for the crawler alone points to a CDN rule, a firewall filter or a JavaScript wall.
Changed 2026-10-10. llms.txt no longer costs points: no engine documents using it, and Google says Search does not read it. ChatGPT-User and Perplexity-User fetch a page because a person asked, and their vendors say robots.txt may not apply to them. A robots.txt rule against either costs 10 points, not 25. A refusal by the server or CDN still costs 25.
kestreloutdoor.com/rain-jackets/summit-shell
-
BrowserA normal visit
200Page served
-
ClaudeBot user-agentSame page, Claude’s user-agent
CDN bot rule403Challenge page: “Checking your browser before accessing…”
-
GPTBot user-agentSame page, GPTBot’s user-agent
200Page served
Fix the block, then keep the site open.
A check tells you what blocks crawlers today. Monitoring tells you when a new rule shuts one out, and whether the crawlers that can reach you actually come.
-
Fix the file
The templates pack carries the robots.txt lines your result asks for, including a group that lets the live answer crawlers in.
Open the templates pack -
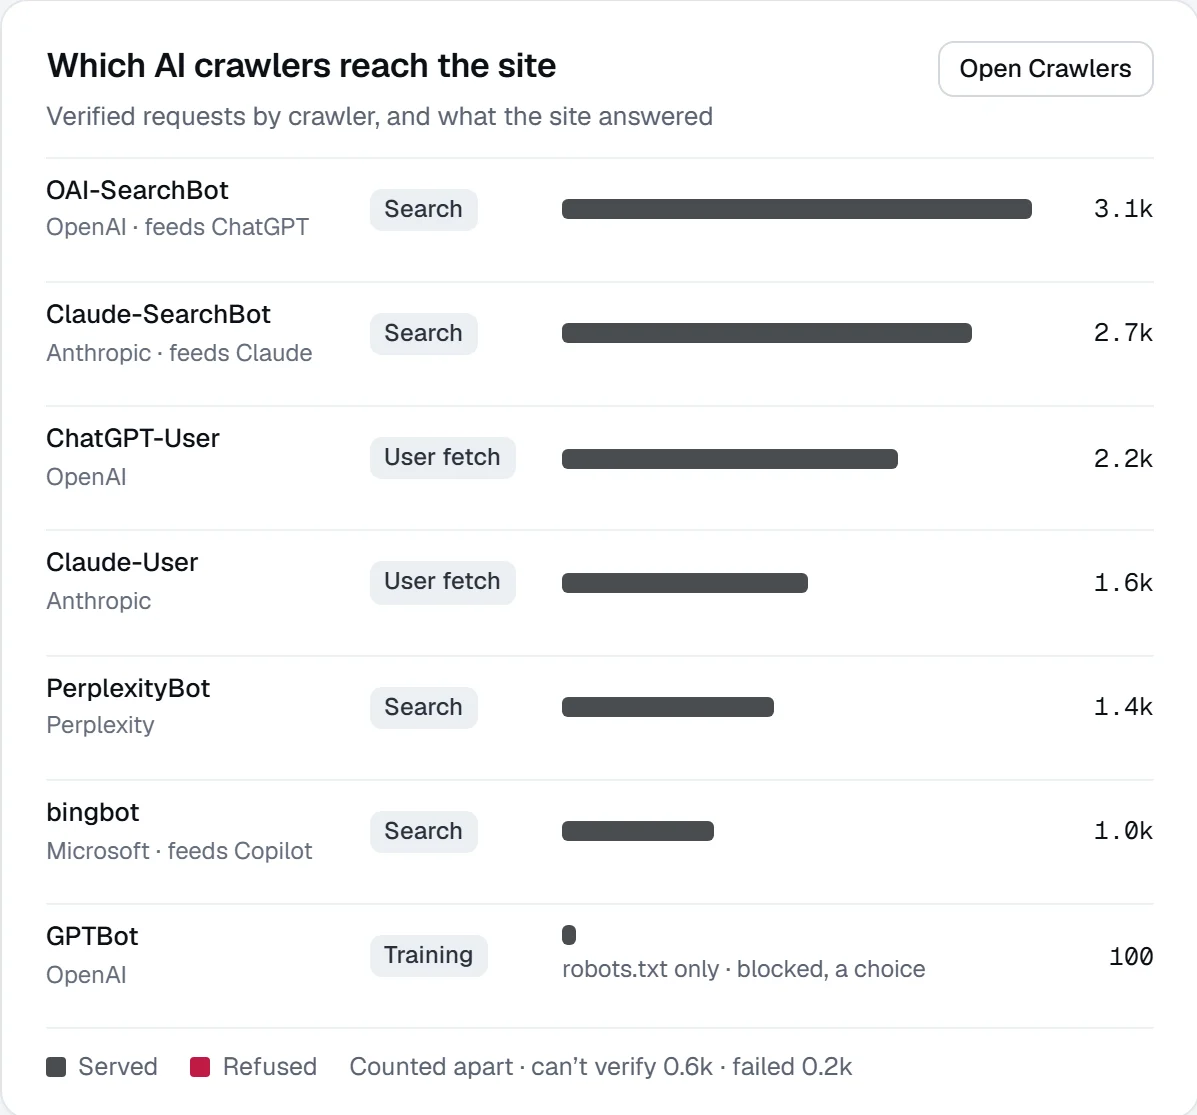
Monitor crawler access
Re-run the check on a schedule and get an alert the moment a crawler’s access changes, with the requests each crawler really made.
Explore AI traffic & conversions -
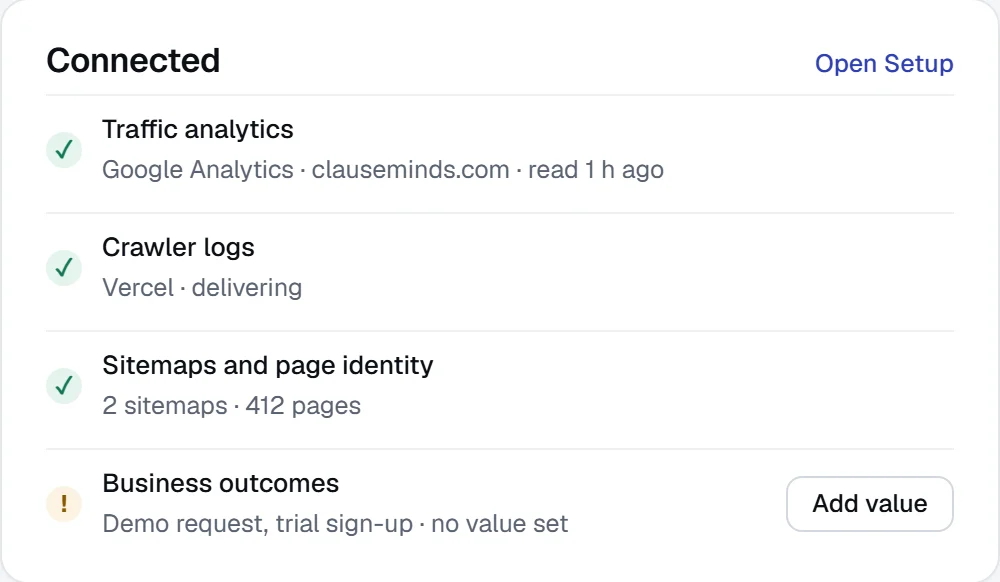
Count verified crawler visits
Connect your crawler logs to count the requests each AI crawler really made, verified rather than guessed from the user-agent.
Explore integrations -
Check the pages they reach
Once crawlers can fetch the site, check how ready each page is to be quoted.
Check a page free
More free tools.
All free toolsQuestions, answered.
Something else on your mind? Contact us.
The live answer-fetch crawlers: ChatGPT-User, Claude-User and Perplexity-User. They fire when somebody asks an AI tool a question and the AI tool goes to read a page to answer. Refusing those at the server removes you from answers being written right now. A robots.txt rule may not stop all of them: OpenAI and Perplexity say their user fetchers may not follow it. Next are the index crawlers (OAI-SearchBot, PerplexityBot, Claude-SearchBot, Applebot), which decide whether you can be retrieved at all.
Only if you want your content kept out of future model training. They collect training data, and blocking them doesn’t affect whether you can be cited today. Make sure the rule names them alone and doesn’t catch the live and index crawlers too.
Then something between the crawler and your content is refusing the request: a CDN bot-management rule, a WAF, a rate limiter, or an interstitial challenge page. That gap is the reason this check sends real requests instead of only reading the file.
No. A clean result means the crawlers can fetch your pages. Whether an engine quotes a page depends on what the page says and how the page is built, which the website checker scores next.
Know the moment a crawler is shut out.
The blocks that hurt most are the ones nobody made on purpose: a CDN bot rule enabled during an incident, a WAF update, a robots.txt line added by a plugin. Monitoring re-runs this check on a schedule and alerts you when access changes.