Skip to content
Why GEO Why us Pricing
Get started free
HomeProduct

Measure the answer. Fix what’s losing. Prove it moved.

Praised is a GEO platform that measures whether AI assistants name your brand, then turns what it finds into fixes you can ship and prove.

The loop

Where each surface sits in the cycle

Measure — buyer prompts run across every engine on a schedule, sampled enough times to give a rate with an interval.

Improve — findings become a prioritised queue that closes only when a re-check confirms the page changed.

Prove — a baseline before and a treatment after, reported with a confidence interval.

Repeat — agents and flows carry the parts of that loop you would otherwise redo by hand every week.

A number with no next action is a report, and a report changes nothing.

Three moves, on repeat

Most tools in this category stop after the first move. A number with no next action is a report, and a report does not change what ChatGPT says about you next month.

Measure

Ask the real questions, repeatedly

A suite of buyer prompts runs on a schedule across every engine, each asked several times, so the result is a sample with an interval rather than one screenshot.

Visibility tracking →

Improve

Turn findings into tracked work

Audits, crawler checks and lost prompts become a prioritised queue. Each item closes only when a re-check confirms the page actually changed. Work it by hand, or hand the repetitive parts to an agent.

Fix queue & site health → Agents →

Prove

Attribute the lift, or don't claim it

A baseline run, your change, a treatment run. The result is a difference with a confidence interval — including when the honest answer is "no measurable change".

Experiments & proof →

The ten surfaces

Each has its own page, because each answers a different question your team will actually ask this quarter.
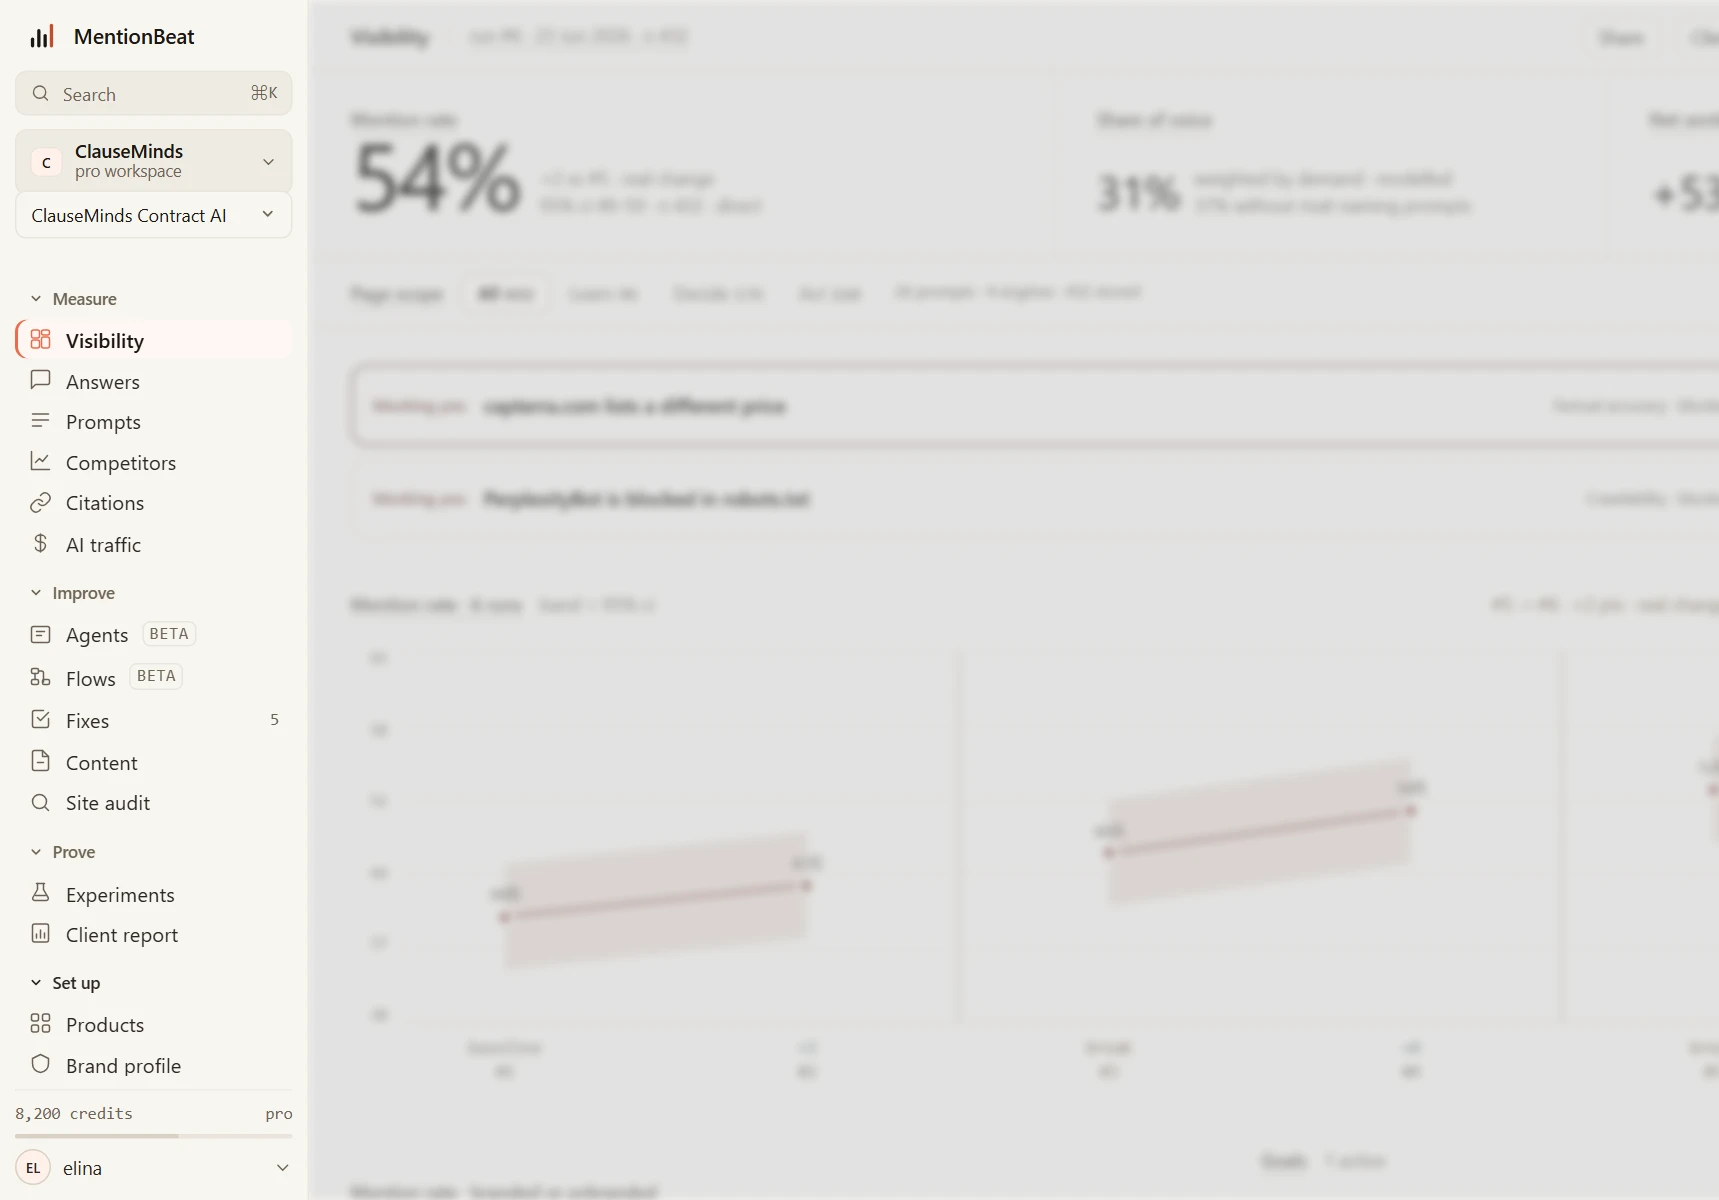
The console rail in focus with a measurement screen soft behind it: Measure (Visibility, Answers, Prompts, Competitors, Citations, AI traffic), Improve (Agents and Flows, both marked Beta, then Fixes, Content, Site audit), Prove (Experiments, Report) and Set up (Products, Brand profile).
Demo workspaceThe rail is the product: measure on top, improve in the middle, prove at the foot. Each row in the table below has its own page.
SurfaceThe question it answersWhat you leave with
Visibility trackingWhere do we stand, and is the change real?Visibility Index, share of voice, mention and recommendation rate — each with an interval
Answers & competitorsWhat did the engine actually say, and who beat us?Verbatim answers per prompt and engine, a rival leaderboard, the domains being cited
AgentsCan something else do this part for me?40 tools on your own data, 3 autonomy modes, a priced estimate and a step-by-step trace
FlowsCan we run the same method every week?A branching graph you draw, priced before it runs and scheduled daily or weekly
Fix queue & site healthWhat do we fix first, and did it land?A crawl-wide audit, per-crawler access verdicts, and a queue that closes on verification
Content StudioWhat exactly do we publish?Page families built from your approved facts, scored 0–100 before they ship
Accuracy & correctionsWhat are engines getting wrong about us?Wrong facts with the source they came from, plus drafted correction requests
Experiments & proofDid any of this work?Measured lift between two runs, attributed to the change that caused it
Integrations & APIHow does this reach the rest of our stack?REST API and keys, Slack and email digests, CSV and PDF export, CMS publishing, SSO
Credits & plansWhat does a run cost before we start it?Priced runs, weighted by engine, with a ceiling you set

What the loop assumes about you

Nothing, at the start. You can run a first measurement with a domain and nothing else — Praised reads your site, proposes a product brief and a prompt suite, and you edit both before anything runs.

  • No tag, no script, no site change to begin measuring
  • No CMS connection unless you want it to publish
  • No credit card on the free tier
  • Every generated prompt is yours to approve, reword or retire

The honesty rule, everywhere

Every number carries how it was produced. A result is labelled live, modeled or estimated; a rate carries its confidence interval; a run that could not reach an engine says so rather than quietly averaging over the gap.

The full method — including its limits and what we deliberately do not do — is published, not summarised. It goes as far as measuring our own instrument: an LLM scores the answers, so the page reports that judge's agreement with hand-labelled answers as Cohen's κ, its sensitivity and specificity, and the correction they drive. Intervals are 2,000-resample cluster bootstraps over prompts rather than responses, and the label counts behind each calibration are printed beside it, so the part of a run the estimate does not cover stays visible.

Read the methodology →

Questions about the platform

Do I have to use the whole loop?
No. Most teams start with measurement alone and stay there for a few runs, because you cannot prioritise a fix before you know which prompts you lose. The improve and prove halves become useful once you have a baseline worth moving.
How long does a full cycle take?
A measurement run takes minutes to hours depending on suite size and engine mix. The loop itself runs on a weekly cadence by default: measure, work the queue, publish, re-measure. Page and retrieval fixes can show up in the next run; entity and reputation work compounds over quarters.
Does Praised change my website?
Only if you connect a CMS and ask it to. By default the Content Studio produces drafts and exports; publishing is an explicit action. Nothing is written to your site without a connection you set up.

Start with one measured run.

See where you actually stand across ChatGPT, Claude, Gemini, Perplexity and AI Overviews — then decide how much of the loop you need.

Free forever plan · 1,500 credits · no card